Fake Artifact
A test app with fake artifact names
No AI needed
not yet reviewed by publik. It is live now; the founder has not reviewed this version yet.
by 
Listed on @sharkdp’s behalf — not claimed yet.
How to install Fake Artifact
Every step written out. No terminal experience needed. Pick your setup.
README
Open in GitHubhyperfine
A command-line benchmarking tool.
(hyperfine in action, benchmarking mypy and ty)
Features
- Statistical analysis across multiple runs.
- Support for various performance metrics and hardware counters.
- Support for arbitrary shell commands.
- Constant feedback about the benchmark progress and current estimates.
- Warmup runs can be executed before the actual benchmark.
- Cache-clearing commands can be set up before each benchmark run.
- Statistical outlier detection to detect interference from other programs and caching effects.
- Export results to various formats: CSV, JSON, Markdown, AsciiDoc.
- Parameterized benchmarks (e.g. vary the number of threads).
- Cross-platform
Usage
Basic benchmarks
To run a benchmark, you can simply call hyperfine <command>.... Each argument is an executable
and its arguments. Commands run directly by default; use -S for shell syntax such as
pipes, redirections, and wildcards. For example:
hyperfine 'sleep 0.3'
Hyperfine will automatically determine the number of runs to perform for each command. By default,
it will perform at least 10 benchmarking runs and estimate a run count targeting roughly
3 seconds, including shell overhead and preparation and conclusion commands. To set an exact
number of runs, you can use the -r/--runs option:
hyperfine --runs 5 'sleep 0.3'
If you want to compare different programs, you can pass multiple commands:
hyperfine 'hexdump file' 'xxd file'
Commands run and appear in input order. The first command is the reference for all comparisons; each subsequent result shows its change from that reference.
Warmup runs and preparation commands
For programs that perform a lot of disk I/O, the benchmarking results can be heavily influenced by disk caches and whether they are cold or warm.
If you want to run the benchmark on a warm cache, you can use the -w/--warmup option to
perform a certain number of program executions before the actual benchmark:
hyperfine -S --warmup 3 'grep -R TODO *'
Conversely, if you want to run the benchmark for a cold cache, you can use the -p/--prepare
option to run a special command before each benchmark run. For example, to clear Linux filesystem caches,
you can run
sync; echo 3 | sudo tee /proc/sys/vm/drop_caches
To use this specific command with hyperfine, call sudo -v to temporarily gain sudo permissions
and then call:
hyperfine -S --prepare 'sync; echo 3 | sudo tee /proc/sys/vm/drop_caches' 'grep -R TODO *'
Parameterized benchmarks
If you want to run a series of benchmarks where a single parameter is varied (say, the number of
threads), you can use the -P/--parameter-scan option and call:
hyperfine --prepare 'make clean' --parameter-scan num_threads 1 12 'make -j {num_threads}'
This also works with decimal numbers. The -D/--parameter-step-size option can be used
to control the step size:
hyperfine --parameter-scan delay 0.3 0.7 -D 0.2 'sleep {delay}'
This runs sleep 0.3, sleep 0.5 and sleep 0.7.
For non-numeric parameters, you can also supply a list of values with the -L/--parameter-list
option:
hyperfine -L compiler g++,clang++ '{compiler} -O2 main.cpp'
A common use case is comparing the same command across multiple Git branches. Use --setup
to switch branches once before each set of benchmark runs, so the branch switch is not part of
the measured command:
hyperfine \
    --parameter-list branch main,performance-improvements \
    --setup 'git switch {branch}' \
    'python main.py'
If you need a unique value for each individual run of a benchmark command, hyperfine also exposes
the zero-based $HYPERFINE_ITERATION environment variable inside the benchmarked command itself:
hyperfine -S 'my-command > output-${HYPERFINE_ITERATION}.log'
Intermediate shell
By default, benchmarked commands, including warmup runs, are executed directly, without an intermediate shell (--shell=none).
Arguments are split using shell-like quoting, so quoted arguments containing spaces are supported.
Shell syntax such as pipes, redirections, environment-variable expansion, *, and ~ is not interpreted.
This avoids shell startup overhead and the noise from correcting for it, especially for fast commands
(< 5 ms).
Commands containing unquoted, standalone shell operators such as && or > require an explicit
choice: use -S / --shell=default to interpret shell syntax, or -N / --shell=none to pass
the operators as literal arguments.
To enable shell syntax, use -S (an alias for --shell=default). This selects sh
on Unix (resolved through PATH) or cmd.exe on Windows:
hyperfine -S 'sleep 0.1 && echo done'
You can also select a specific shell with --shell <SHELL>:
hyperfine --shell zsh 'for i in {1..10000}; do echo test; done'
The --setup, --prepare, --conclude, and --cleanup commands always run through a shell.
They use the shell selected by --shell, or the platform shell (sh on Unix, cmd.exe on Windows)
when --shell is omitted or set to none.
When benchmarked commands use a shell, hyperfine corrects for the shell spawning time. It runs the shell with an empty command multiple times to measure its startup time, then subtracts this time from each time measurement.
Shell functions
If you are using bash, you can export shell functions to directly benchmark them with hyperfine:
my_function() { sleep 1; }
export -f my_function
hyperfine --shell=bash my_function
Otherwise, inline the function into the benchmarked command:
hyperfine -S 'my_function() { sleep 1; }; my_function'
Environment variables
Use --env to set environment variables for benchmark commands and their respective setup, prepare, conclude,
and cleanup commands. Assignments are space-separated and support shell-style quoting,
but no shell expansion:
hyperfine --env 'OMP_NUM_THREADS=8 CFLAGS="-O3 -march=native"' 'my_command'
Specify once for all commands or once per benchmark command:
hyperfine \
  --env 'OMP_NUM_THREADS=8' './benchmark-cpp' \
  --env 'RAYON_NUM_THREADS=8' './benchmark-rust'
Use an empty --env='' for no overrides. Values can contain parameter placeholders.
For example, the following benchmarks my_command with OMP_NUM_THREADS ranging from 1 to 8:
hyperfine -P threads 1 8 --env 'OMP_NUM_THREADS={threads}' 'my_command'
Choosing metrics and units
By default, hyperfine displays wall-clock time and memory usage
(time_wall_clock,memory_peak_resident). Use --metrics with a
comma-separated list to select a different set of metrics. Each
metric can have an optional unit after it:
hyperfine \
    --metrics memory_peak_resident:MiB,time_wall_clock:ms,instructions \
    './baseline' './candidate'
The following metrics are available:
-
time_wall_clock: Time from start to finish, including time spent waiting, in seconds. -
time_user: CPU time spent executing application and library code in user mode, summed across threads, in seconds.- Linux/macOS: Includes child-process time when parents wait for their children to finish.
- Windows: Includes the command and its child processes.
-
time_system: CPU time spent executing kernel code on the program's behalf, for example to read files, summed across threads, in seconds.- Linux/macOS: Includes child-process time when parents wait for their children to finish.
- Windows: Includes the command and its child processes.
-
time_cpu: Total CPU time, calculated astime_user + time_systemfor each run, in seconds. It excludes time spent sleeping or waiting without executing. CPU time is summed across threads, so it can exceed wall-clock time: four threads running on four cores for one second can consume roughly four CPU-seconds. -
memory_peak_resident: Peak memory held in physical RAM, in bytes.- Linux/macOS: Peak resident set size (RSS). This is the largest per-process peak among the command and child processes (whose usage is collected when their parents wait for them), not the simultaneous total memory of the full process tree. On Linux, measuring commands with a very small peak RSS (below the peak inherited from hyperfine at startup, which can be a few MiB) will currently result in that inherited value being reported instead.
- Windows: Currently not supported.
-
cpu_cycles: CPU cycles consumed.- Linux: Includes threads and child processes, but excludes kernel and hypervisor execution.
- macOS: Includes the process's threads and kernel execution, but excludes child processes.
- Windows: Currently not supported.
-
instructions: Completed CPU instructions.- Linux/macOS: Same scope as
cpu_cycles. - Windows: Currently not supported.
- Linux/macOS: Same scope as
-
cache_references: Cache accesses counted by the CPU's generic cache event.- Linux: Same scope as
cpu_cycles. Cache-event definitions depend on the CPU. - macOS/Windows: Currently not supported.
- Linux: Same scope as
-
cache_misses: Cache misses.- Linux: Same scope as
cpu_cycles. Cache-event definitions depend on the CPU. - macOS/Windows: Currently not supported.
- Linux: Same scope as
-
branch_misses: Mispredicted branches.- Linux: Same scope as
cpu_cycles. - macOS/Windows: Currently not supported.
- Linux: Same scope as
Note that hardware counters are not available when a shell is enabled (--shell=..).
Time measurements support units ns, us, ms, s, min, and h. Memory measurements
support B, kB, MB, GB, TB, KiB, MiB, GiB, and TiB. Hardware counters
support count (1), k (thousand), M (million), and B (billion).
You can also use a preset to select a group of metrics:
| Preset | Metrics |
|---|---|
--metrics=default | time_wall_clock,memory_peak_resident |
--metrics=time | time_wall_clock,time_cpu,time_user,time_system |
--metrics=all | All available metrics |
Exporting results
Hyperfine can export results to CSV, JSON, Markdown, AsciiDoc, and org-mode. CSV exports all
selected metrics, while Markdown, AsciiDoc, and org-mode contain only the primary metric,
which is the first metric selected by --metrics.
Markdown
You can use the --export-markdown <file> option to create tables like the following:
| Command | Mean Wall Time [s] | Change | Factor |
|---|---|---|---|
find . -iregex '.*[0-9]\.jpg$' | 2.275 ± 0.046 | ||
find . -iname '*[0-9].jpg' | 1.427 ± 0.026 | -37.3% | (1.6x faster) |
fd -HI '.*[0-9]\.jpg$' | 0.232 ± 0.002 | -89.8% | (9.8x faster) |
JSON
The JSON export includes all available metrics listed in Choosing metrics and units for each measured run (excluding warmup runs).
The JSON output is useful if you want to analyze the benchmark results in more detail. The
scripts/ folder includes a lot
of helpful Python programs to further analyze benchmark results and create helpful
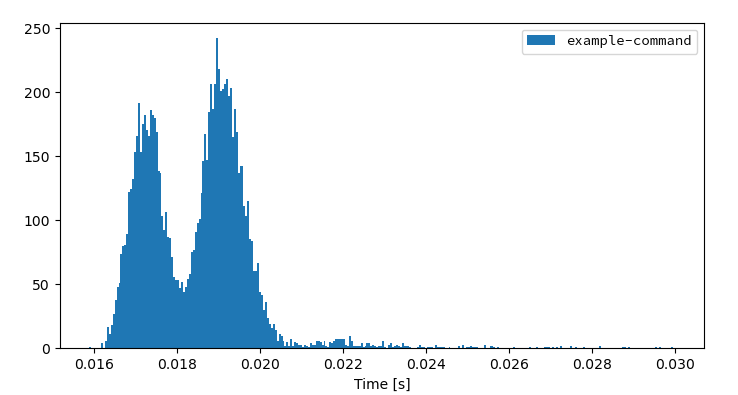
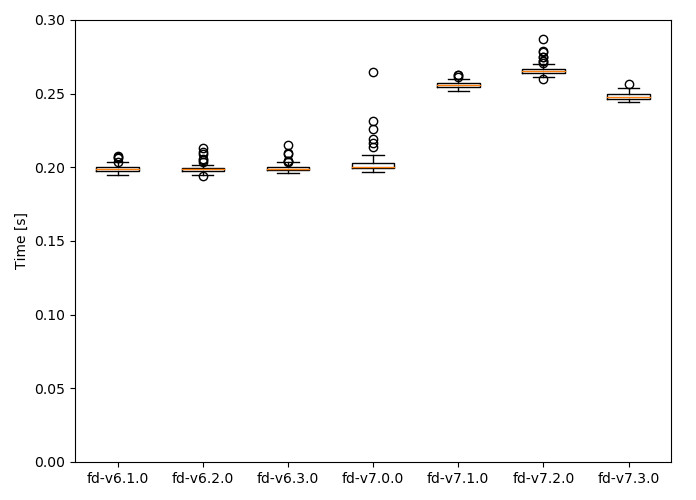
visualizations, like a histogram of runtimes or a whisker plot to compare
multiple benchmarks.
For example, these two commands create the following plots:
uvx --from 'git+https://github.com/sharkdp/hyperfine' \
  plot_histogram results.json
uvx --from 'git+https://github.com/sharkdp/hyperfine' \
  plot_whisker results.json
 |  |
|---|
CSV
Use --export-csv <file> to export one row per command. Each metric selected by --metrics
contributes a group of columns, in selection order: <metric>_unit, <metric>_mean,
<metric>_stddev, <metric>_median, <metric>_min, and <metric>_max.
CSV uses explicitly selected units, or base units (seconds, bytes, or counts) when omitted.
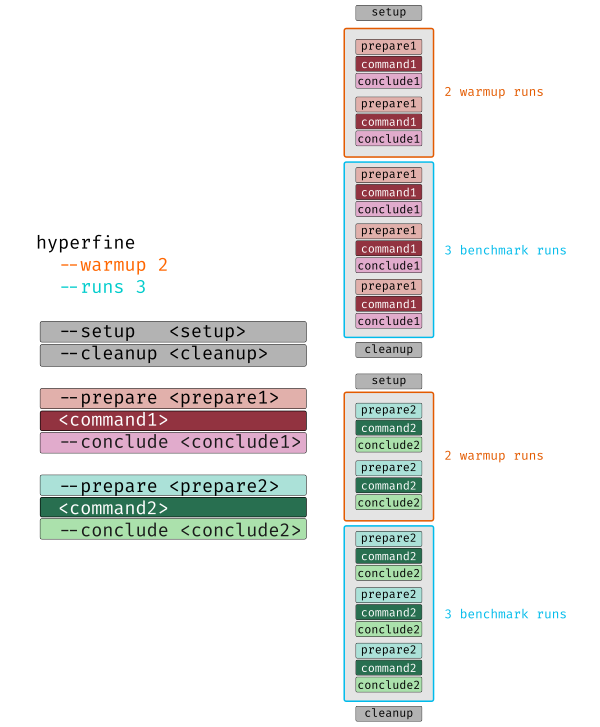
Detailed benchmark flowchart
The following chart explains the execution order of various benchmark runs when using options
like --warmup, --prepare <cmd>, --setup <cmd> or --cleanup <cmd>:
Alternative tools
Hyperfine is inspired by bench.
Integration with other tools
Chronologer is a tool that uses hyperfine to
visualize changes in benchmark timings across your Git history.
Bencher is a continuous benchmarking tool that supports hyperfine to
track benchmarks and catch performance regressions in CI.
Drop hyperfine JSON outputs onto the Venz chart to visualize the results, and manage hyperfine configurations.
Make sure to check out the scripts folder
in this repository for a set of tools to work with hyperfine benchmark results.
Origin of the name
The name hyperfine was chosen in reference to the hyperfine levels of caesium 133 which play a crucial role in the definition of our base unit of time — the second.
Citing hyperfine
Thank you for considering citing hyperfine in your research work. Please see the information in the sidebar on how to properly cite hyperfine.
License
hyperfine is dual-licensed under the terms of the MIT License and the Apache License 2.0.
See the LICENSE-APACHE and LICENSE-MIT files for details.