Spokesman
Hold a key, talk, and your words type into any Mac app, all on-device.
AI: local or online
not yet reviewed by publik. It is live now; the founder has not reviewed this version yet.
Where Spokesman’s AI runs, and what it costs
Prices are for one typical use: one request of about 1,500 words sent and 375 words back. A higher quality score is better.
On your computer
- Price
- Free per use. Your computer does the work.
- Runs with
- faster-whisper, llama.cpp
- Memory
- Llama 3.1 8B is a 4.9 GB download at 4-bit. gpt-oss 20B runs on systems with as little as 16GB memory. Faster with Apple silicon or a graphics card.
- Quality
- Llama 3.1 8B: 7
publik API
- Price
- $0.0100 per use, $10.00 per 1,000 usespublik-balanced, the default level
- Quality
- MiMo-V2.6-Pro: 46
- Setup
- Not built into Spokesman yet. A publik API key works wherever Spokesman takes an OpenAI-compatible address.
Your own key
- Price
- $0.0013 per use, $1.31 per 1,000 usesMiMo-V2.6-Pro at OpenRouter’s list price, before its fee for buying usage
- Quality
- MiMo-V2.6-Pro: 46
- Setup
- Open a provider account, add a card, paste the key into Spokesman.
Quality and price, side by side
| Model | Quality | Per 1,000 uses |
|---|---|---|
| On your computer (Ollama, 4-bit download size) | ||
| Granite 4.2 3B2.2 GB | 9 | $0 |
| Phi-4 Mini2.5 GB | 6 | $0 |
| Llama 3.1 8B4.9 GB | 7 | $0 |
| gpt-oss 20B14 GB | 9 | $0 |
| Gemma 4 31B20 GB | 19* | $0 |
| Qwen3.5 35B-A3B24 GB | 19* | $0 |
| publik API | ||
| publik-fastGLM-5.3 Flash | 42 | $1.00 |
| publik-balancedMiMo-V2.6-Pro · Spokesman | 46 | $10.00 |
| publik-smartGPT-6 Sol | 48 | $18.00 |
Quality: Artificial Analysis Intelligence Index v4.3.2, read 2026-09-22 (publik API models 2026-09-25); * = estimated by Artificial Analysis. Sizes: the Ollama library, read 2026-09-22.
What you pay for
- On your computer: nothing per use. You pay in disk space, memory and electricity, at lower quality.
- publik API: publik’s published price for each use, in dollars, from your publik balance. It is above the model’s cost; the difference runs publik and pays the app’s builder.
- Your own key: the provider’s price, billed to an account you keep with the provider.
How to install Spokesman
Every step written out. No terminal experience needed. Pick your setup.
README
Open in GitHub
Spokesman
Private, on-device voice-to-text for macOS.
An open-source Wispr Flow alternative. Hold a key, talk, let go, and it types for you in any app.



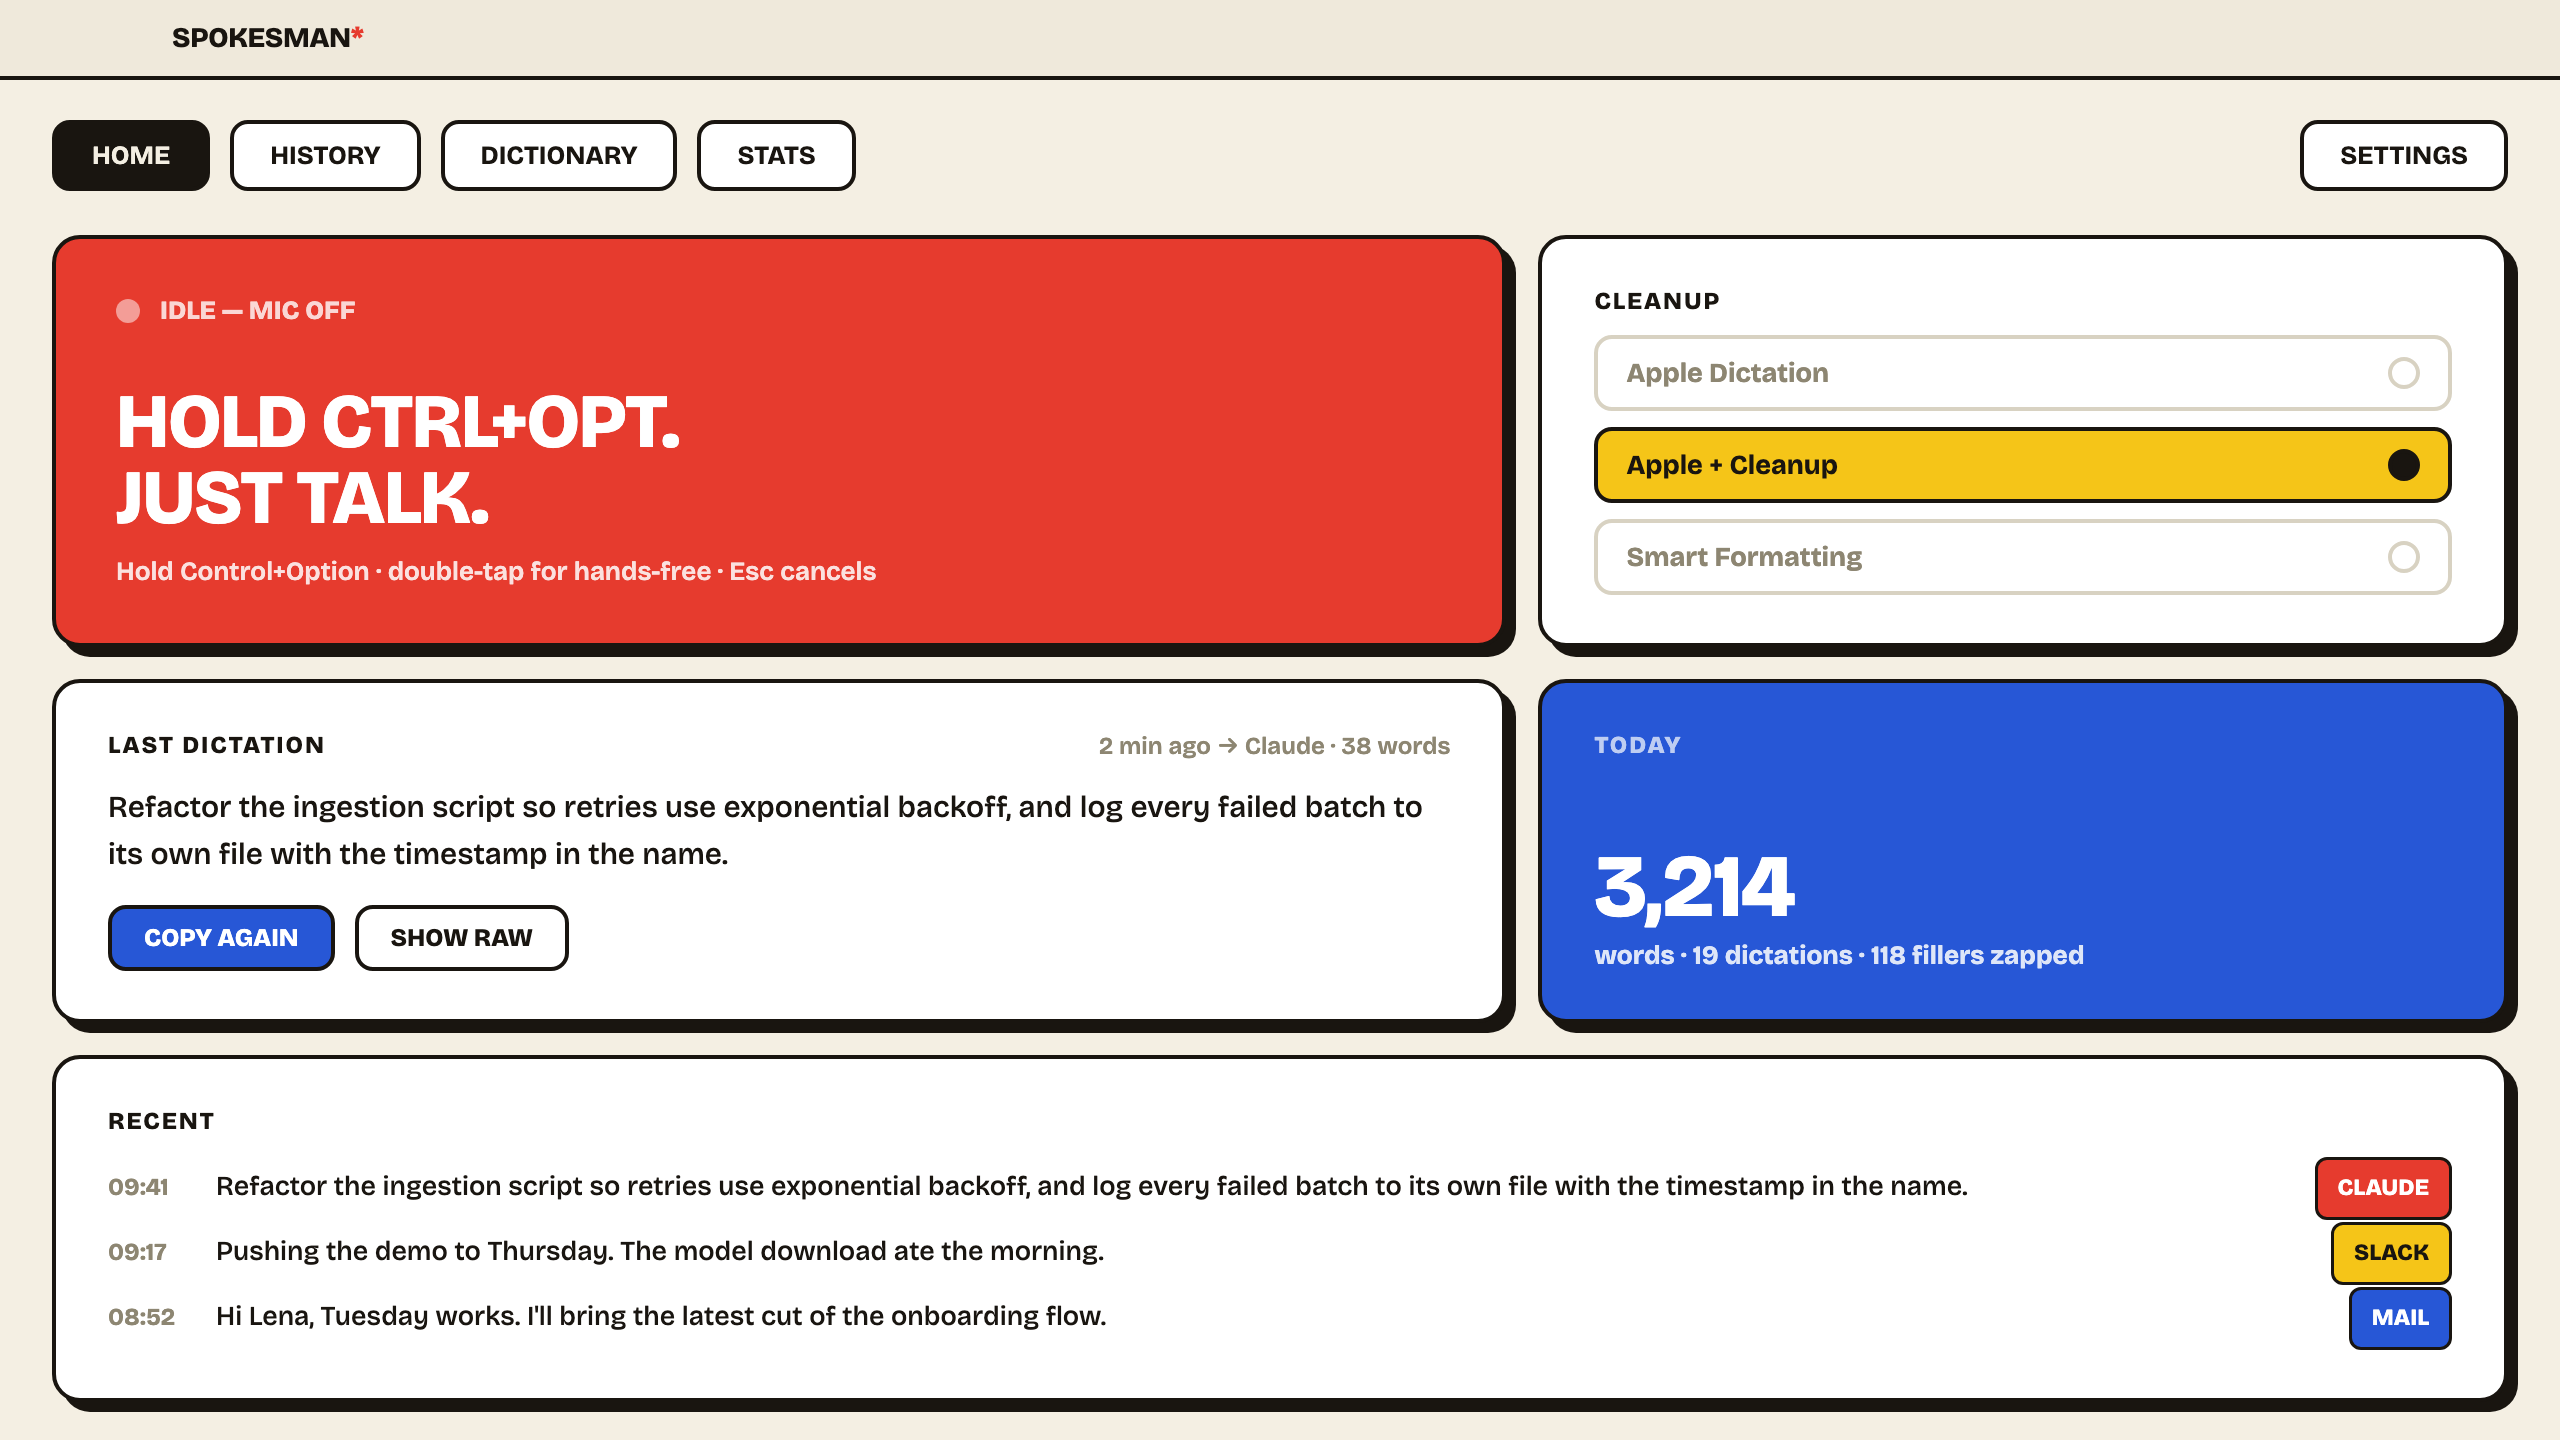
Okay so, Spokesman is a dictation app for Mac. You hold Control+Option, talk like you normally would, let go, and the text just shows up in whatever app you're in. Claude, ChatGPT, Codex, Slack, Mail, your editor, anywhere with a text box.
I built it because I wanted something like Wispr Flow, but that's a subscription and your voice goes to the cloud. I wanted the same feel without either of those. So this runs on Apple's on-device speech model (SpeechAnalyzer + DictationTranscriber), it transcribes while you're still talking so there's barely any wait when you let go, and the audio only lives in memory and then gets thrown away. It never touches disk and it never gets uploaded.
Why I use it
Most of what I dictate is long, messy prompts into Codex and Claude. I say "um", I restart sentences, I go "Tuesday, no, Thursday". I don't want that cleaned into some generic corporate paragraph though, I want it to still sound like me, just without the mess. So the cleanup here is pretty careful about what it touches.
What it does
- Push-to-talk or hands-free. Hold the shortcut to talk, or double-tap it and it keeps recording hands-free.
Esccancels. You can change the shortcut. - Fast, on-device transcription. Apple Dictation runs while you speak and stays warmed up, so the wait after you let go is short.
- Pastes into the app you're in. A small HUD shows you what's happening and it doesn't steal focus from the field you were typing in.
- Cleanup that keeps your voice. Takes out "um", "uh", "like", repeated words and the self-corrections, and leaves your actual phrasing alone.
- Your own dictionary. Add names and jargon once and it steers recognition toward your spelling, instead of guessing and patching words after.
- Learns from your fixes. If you fix a misheard word right after dictating, it picks that up and learns the spelling.
- History and stats. Search everything you've dictated, compare the cleaned text against what you actually said, and see your words, time saved, streaks and top words. All of it stays on your Mac.
- Smart Formatting, if you want it. Bring your own OpenAI key and it'll format dictated text into lists and paragraphs. It's off by default, only the text gets sent (never audio), and if the call fails it just falls back to local cleanup.
- An actual Mac app. Sits in the menu bar, can launch at login, native AppKit. No Electron, no Python, no terminal window you have to keep open.
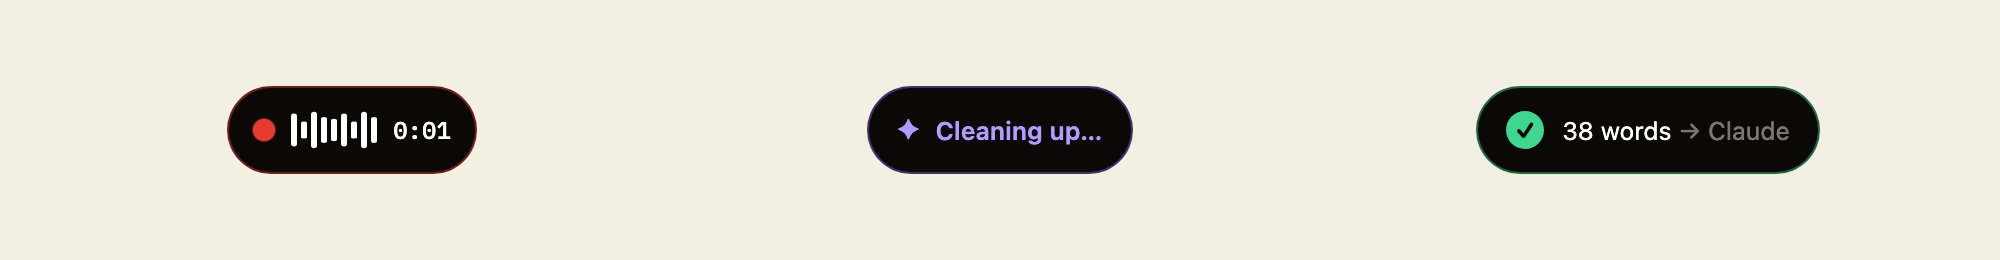
Screenshots
| History | Dictionary |
|---|---|
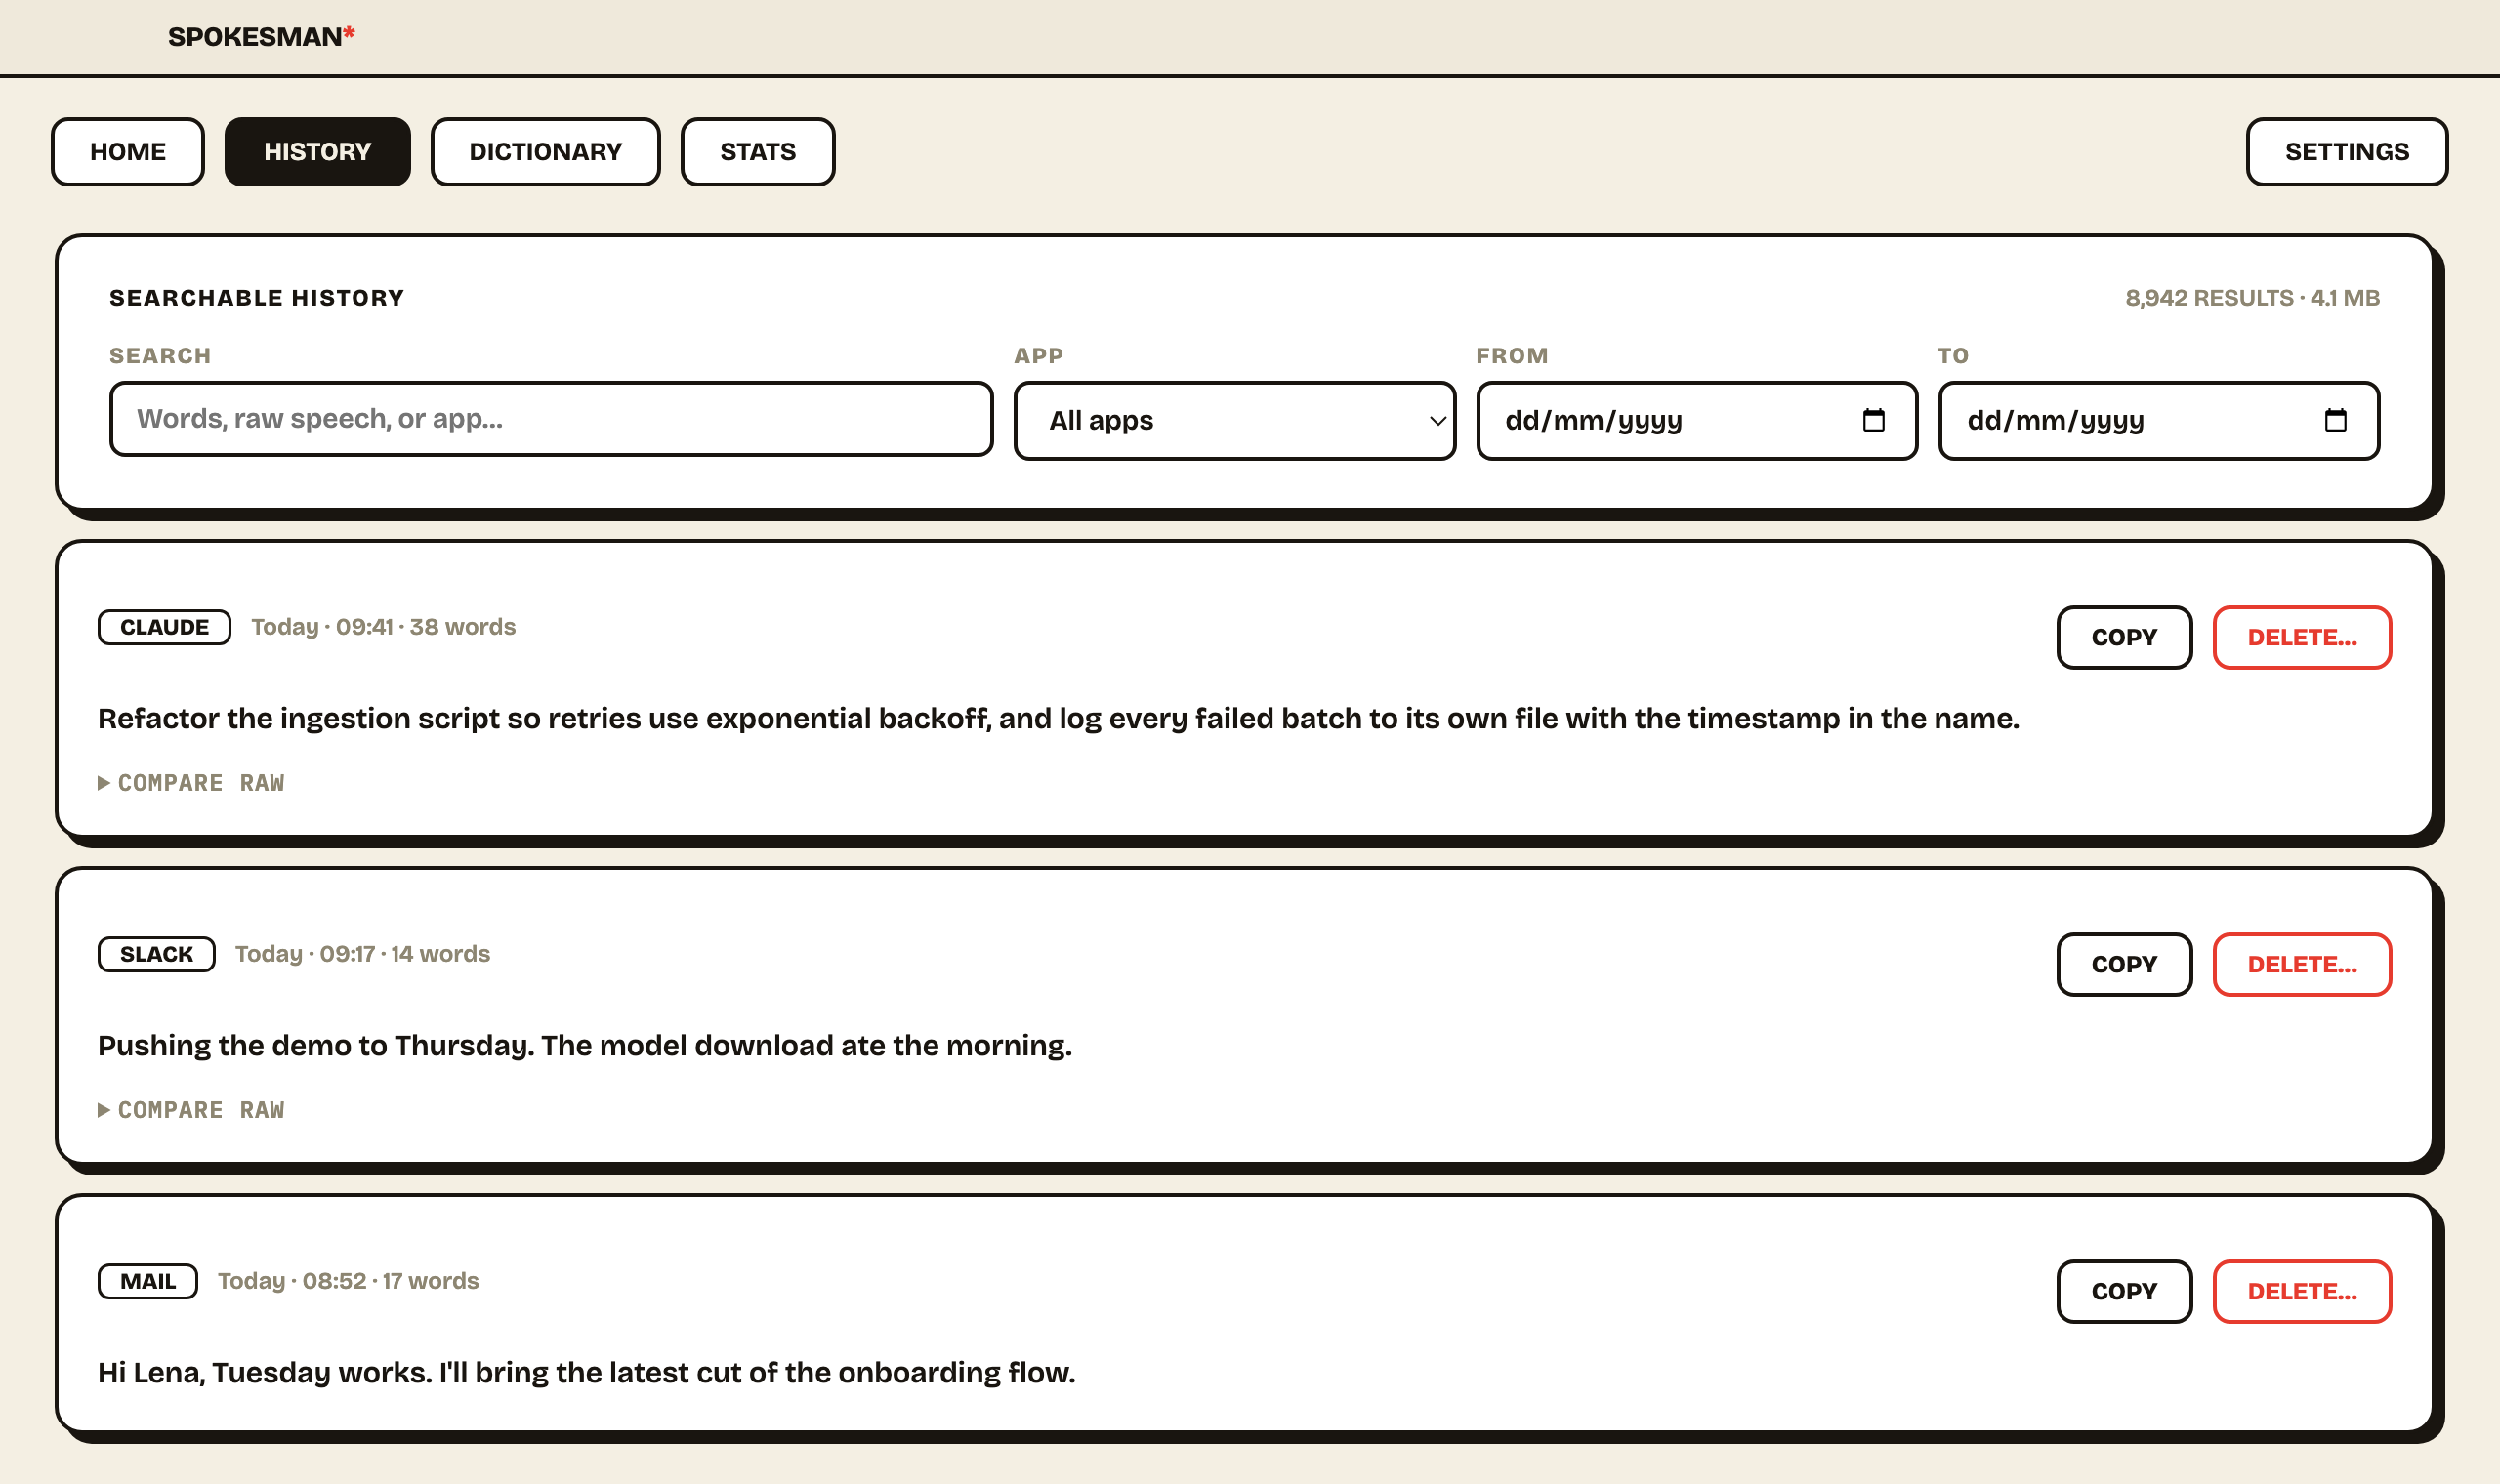 | 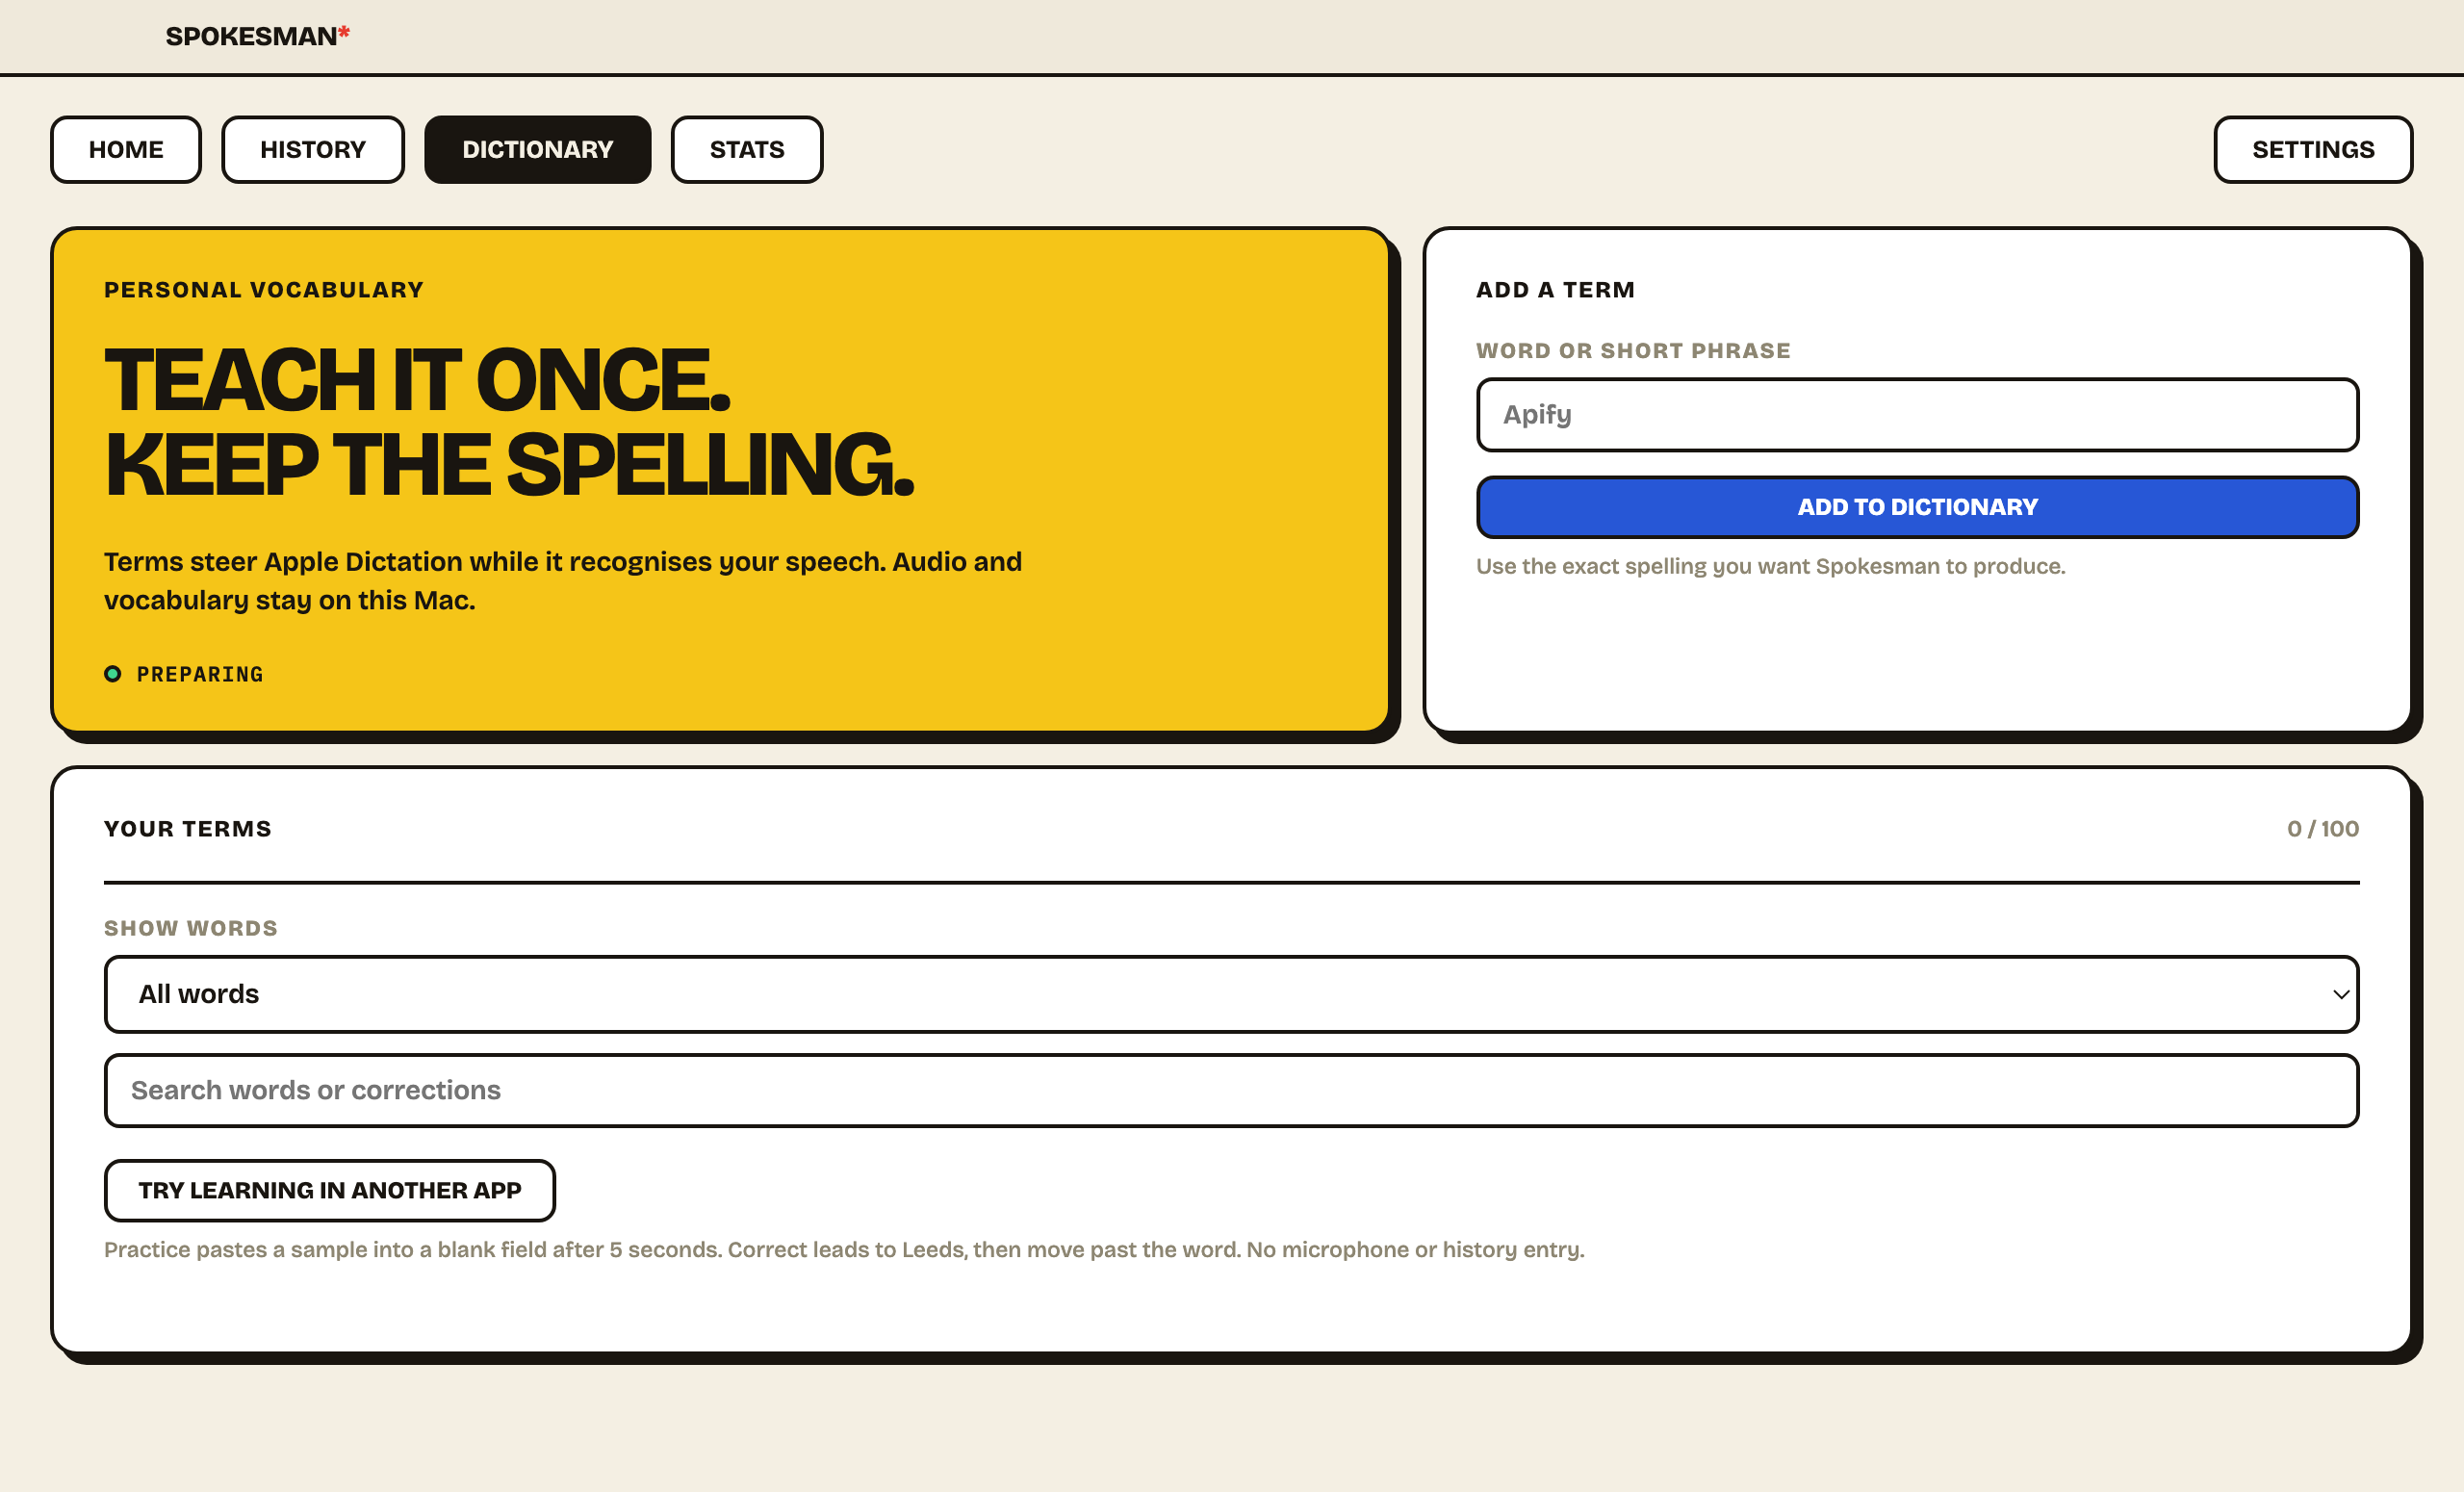 |
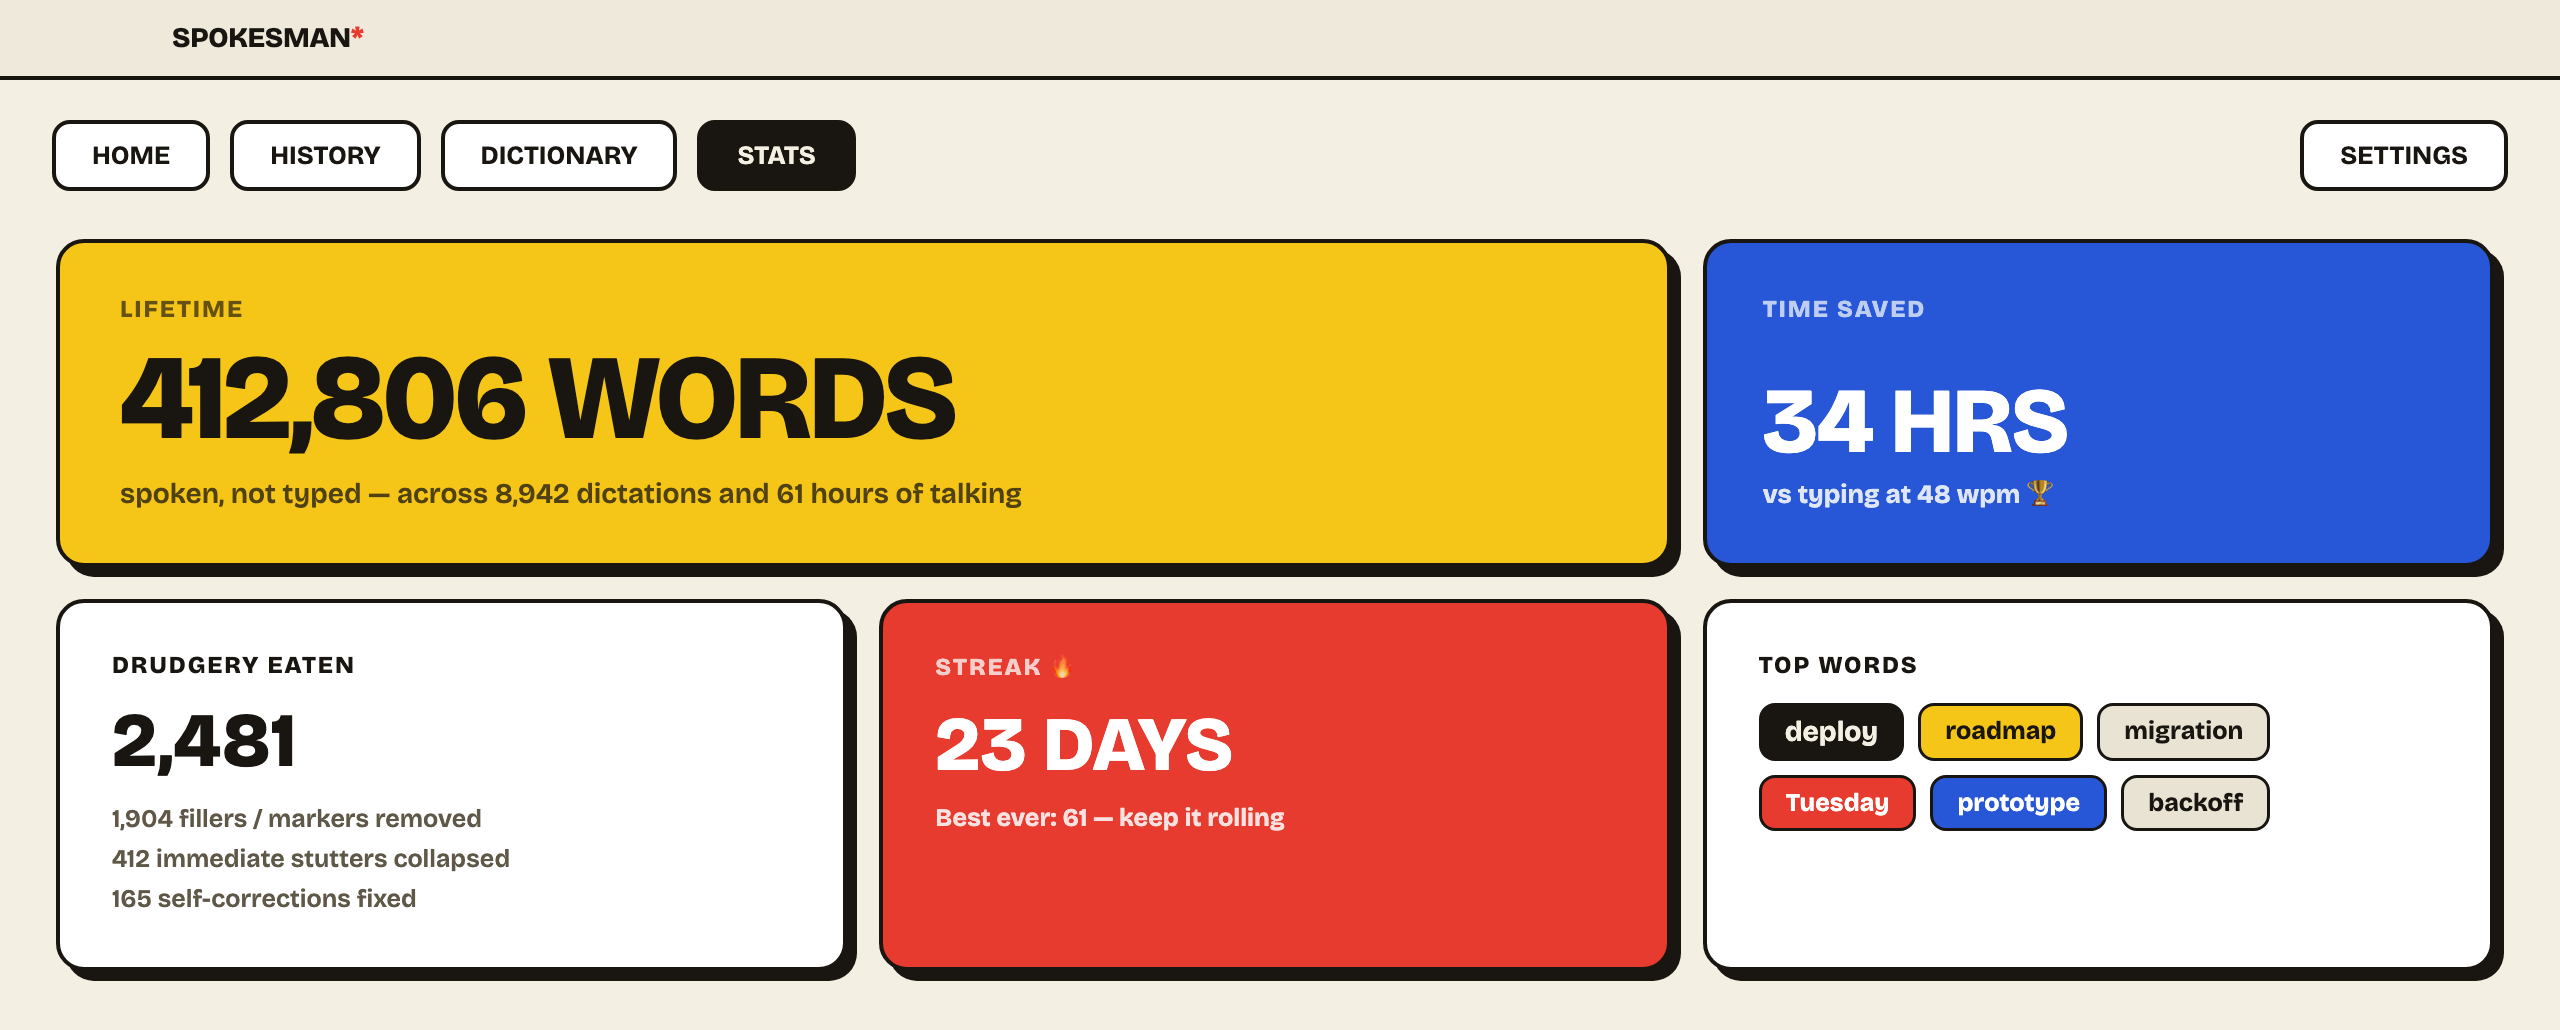
Everything in these screenshots is demo data, not my actual dictations.
Requirements
- macOS 26 (Tahoe) or later (developed and tested on an M1 Pro)
- Xcode 26 (only needed to build it)
Privacy
- Audio is processed in memory and discarded. It's never saved and never uploaded.
- History, stats, and your dictionary live on your Mac. You can prune or erase them.
- No telemetry, no analytics, no crash reporting.
- Nothing leaves your machine unless you turn on Smart Formatting, which sends only the dictated text to OpenAI (with
store: false).
How it works
Control+Option ─► AVAudioEngine (in-memory buffers)
                     │
                     ▼
        SpeechAnalyzer + DictationTranscriber  (on-device, streaming)
                     │   biased by your personal vocabulary
                     ▼
        Local cleanup (fillers, stutters, self-corrections)
                     │   optional: Smart Formatting via your OpenAI key
                     ▼
        Accessibility / CGEvent paste into the focused app
The native app is in macos/ (Swift Package, AppKit, WKWebView dashboard, SMAppService for launch at login). The earlier Windows/Python version is still in src/spokesman/ for reference.
Development
swift test --package-path macos
bash scripts/build-macos-app.sh
Product direction and design notes are in PLAN.md, docs/PRD.md, and DESIGN.md.
Contributing
Issues and PRs are welcome. This started as my own daily driver, so honestly the stuff most likely to get merged is anything that keeps it fast, private and simple. If you're not sure whether something fits, just open an issue and ask.